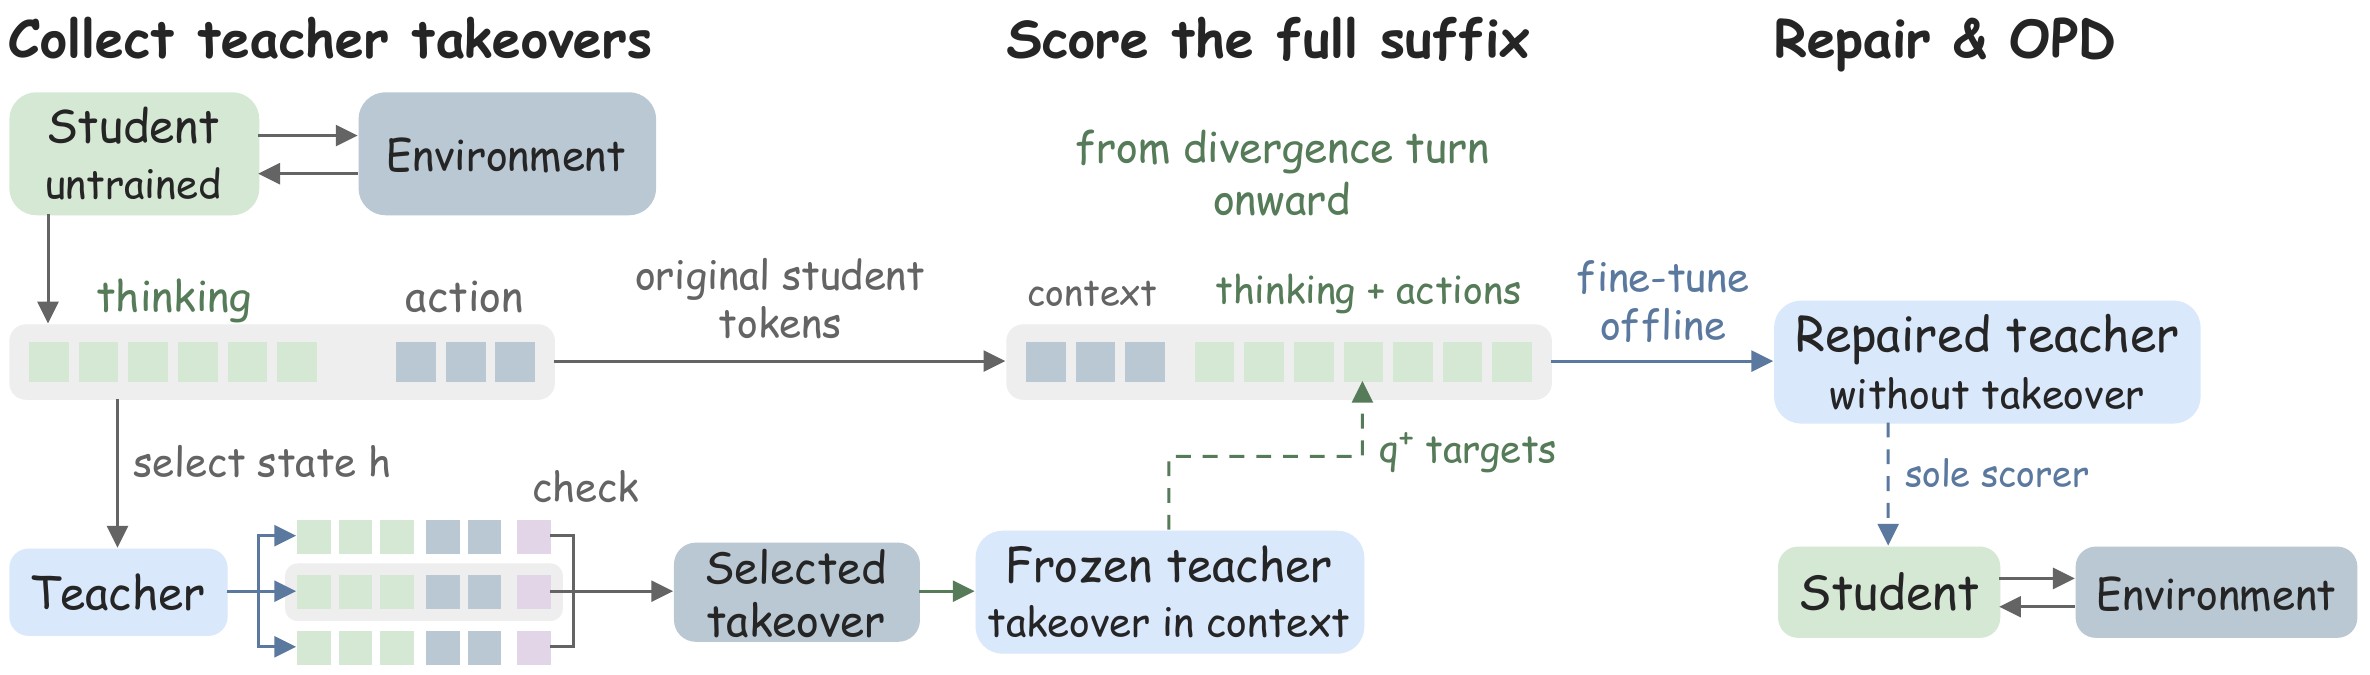
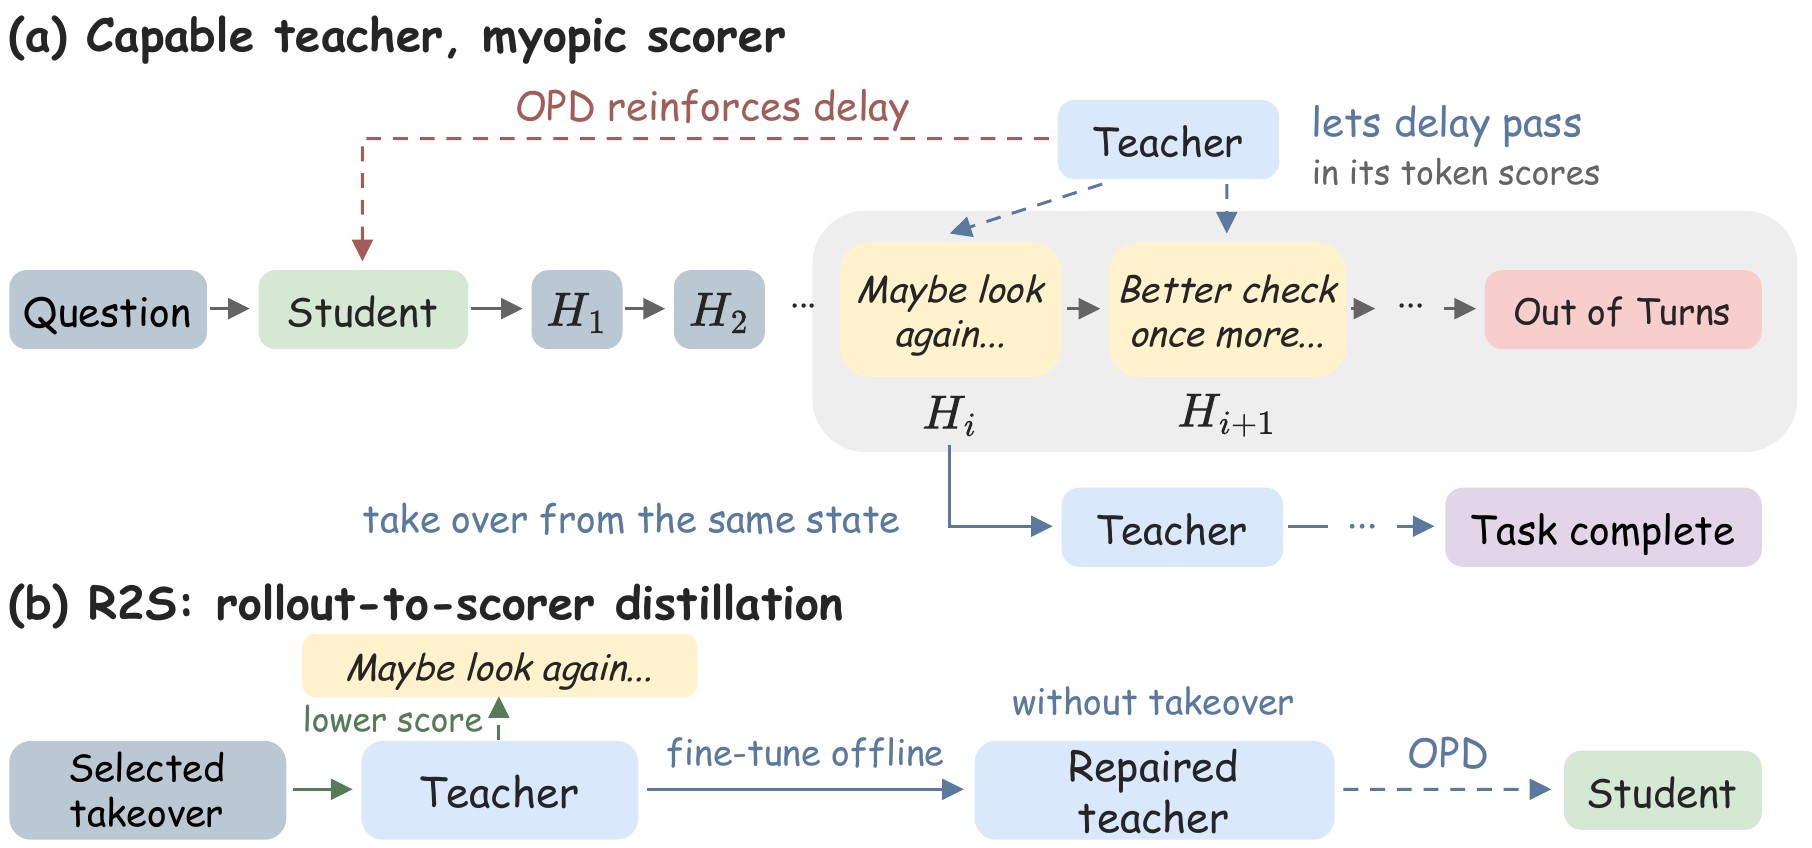
Agentic on-policy distillation (OPD) trains a student agent on its own trajectories while a teacher scores every token. A natural explanation of where it goes wrong is compounding error: the student's mistakes carry its trajectories beyond the region where the teacher is reliable, so recent methods keep training inside that region, through episode-length curricula, teacher-guided turns, prefix replay, or teacher intervention where the two disagree. We show this explanation is incomplete. From the states where the student departs most from the teacher, the teacher's own takeovers still finish the task, yet the student trained on its token scores keeps running out of turns. We attribute this to the myopia of next-token scoring. The teacher rates each token without seeing where the episode ends, so its scores let through the safe, delaying moves that outcome-based RL would punish with zero reward, a penalty agentic OPD lacks. We call this difference between what the teacher does and what it scores the rollout–scorer gap. We propose Rollout-to-Scorer Distillation (R2S), which repairs the scorer before distillation by mining high-disagreement states from the untrained student, running teacher takeovers from them, keeping the states where enough takeovers pass a reward-free check such as consensus or an LLM judge, and fine-tuning the teacher to give its takeover-informed scores on every assistant token from the divergence turn onward, without the takeover in context. The repaired teacher is frozen as the sole scorer for standard OPD, requiring no task reward during repair or training. Across three environments, two teachers and four students, R2S outperforms three state-of-the-art agentic-OPD methods in all twelve teacher–student–environment cells, by 12.8 success points on average over the best of them in each cell.
R2S repairs the teacher's scores on the full assistant suffix before ordinary OPD. With a selected takeover from the untrained student's state in context, the frozen teacher T0 scores the student's thinking and actions from the divergence turn onward (q+). A copy learns these targets without the takeover and becomes the sole OPD scorer.
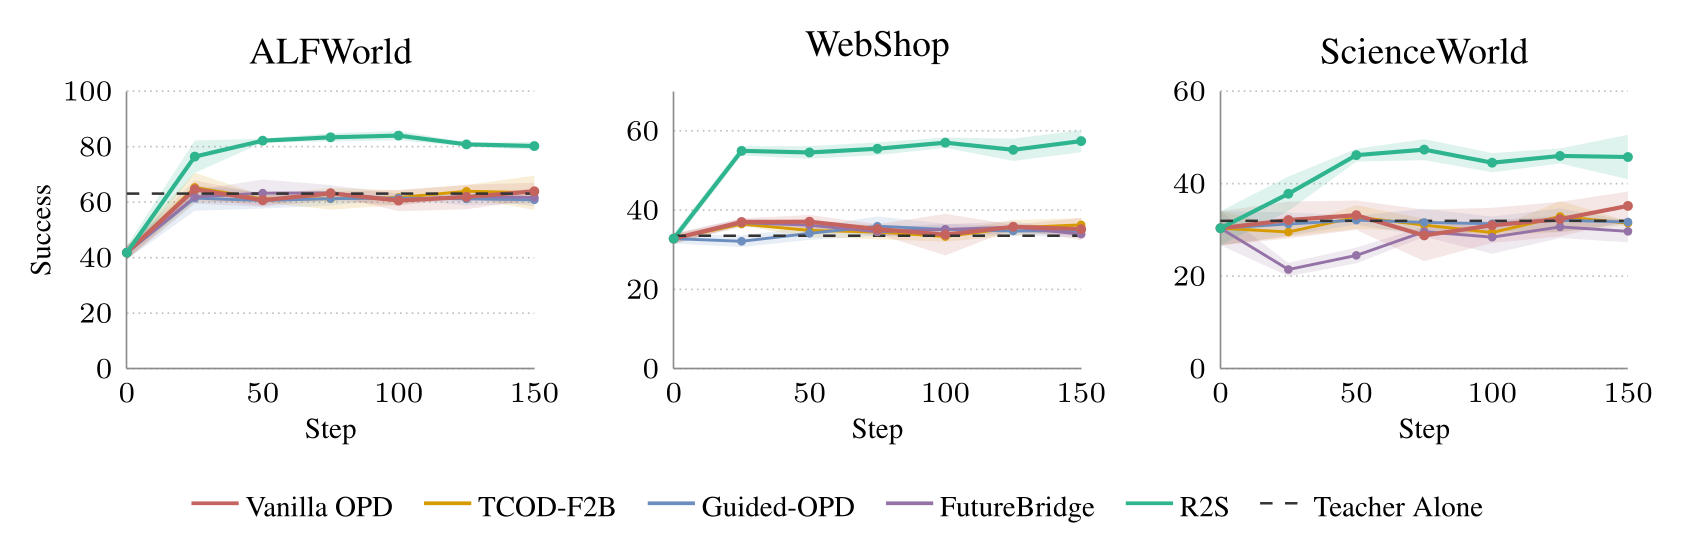
R2S versus vanilla OPD, TCOD-F2B, Guided-OPD and FutureBridge. Success (%) of one training run per cell, mean ± std over three decodes of its final checkpoint. The best and second best of the five trained students in each column are highlighted; the teacher acting alone and the untrained student are anchors.
| Method | ALFWorld | WebShop | ScienceWorld | |||
|---|---|---|---|---|---|---|
| Qwen3.5-9B teaches Qwen3.5-2B and Qwen3.5-4B | ||||||
| 2B | 4B | 2B | 4B | 2B | 4B | |
| Teacher alone | 63.1±1.7 | 33.5±0.3 | 32.0±1.8 | |||
| Student alone | 15.1±1.8 | 43.4±1.0 | 17.6±1.1 | 33.7±0.9 | 3.1±0.4 | 28.0±1.5 |
| Vanilla OPD | 58.0±2.4 | 65.8±2.6 | 35.7±1.6 | 34.6±2.9 | 23.7±2.0 | 34.6±3.5 |
| TCOD-F2B | 62.7±2.0 | 59.6±1.5 | 33.1±0.5 | 35.1±0.9 | 28.0±2.6 | 30.6±0.7 |
| Guided-OPD | 63.6±2.2 | 61.6±2.0 | 35.6±0.6 | 35.5±1.3 | 25.9±3.7 | 32.2±1.1 |
| FutureBridge | 56.8±2.8 | 58.4±3.7 | 36.3±1.0 | 33.9±1.7 | 19.0±2.0 | 30.7±1.3 |
| R2S (ours) | 77.9±1.3 | 81.9±2.4 | 57.9±1.6 | 55.9±1.4 | 37.9±0.6 | 47.8±3.0 |
| Qwen3-30B-A3B-Instruct-2507 teaches Qwen3-4B and Qwen3-8B | ||||||
| 4B | 8B | 4B | 8B | 4B | 8B | |
| Teacher alone | 42.3±1.1 | 2.9±0.3 | 32.9±3.2 | |||
| Student alone | 30.4±2.3 | 46.9±0.8 | 15.5±1.2 | 23.6±1.2 | 9.0±1.4 | 24.0±3.9 |
| Vanilla OPD | 41.2±1.7 | 44.5±2.6 | 24.7±1.1 | 20.3±0.9 | 38.0±1.2 | 36.8±1.0 |
| TCOD-F2B | 42.6±1.1 | 48.8±1.8 | 22.8±0.7 | 23.4±0.7 | 38.4±0.9 | 34.9±0.5 |
| Guided-OPD | 42.0±0.4 | 47.0±1.9 | 23.3±1.6 | 22.3±0.8 | 34.7±1.8 | 33.0±1.5 |
| FutureBridge | 41.8±2.6 | 45.9±1.1 | 16.7±0.9 | 20.7±0.7 | 36.1±1.5 | 37.1±2.0 |
| R2S (ours) | 54.5±1.4 | 54.7±1.0 | 28.5±0.6 | 30.4±1.2 | 45.8±1.4 | 50.5±1.4 |
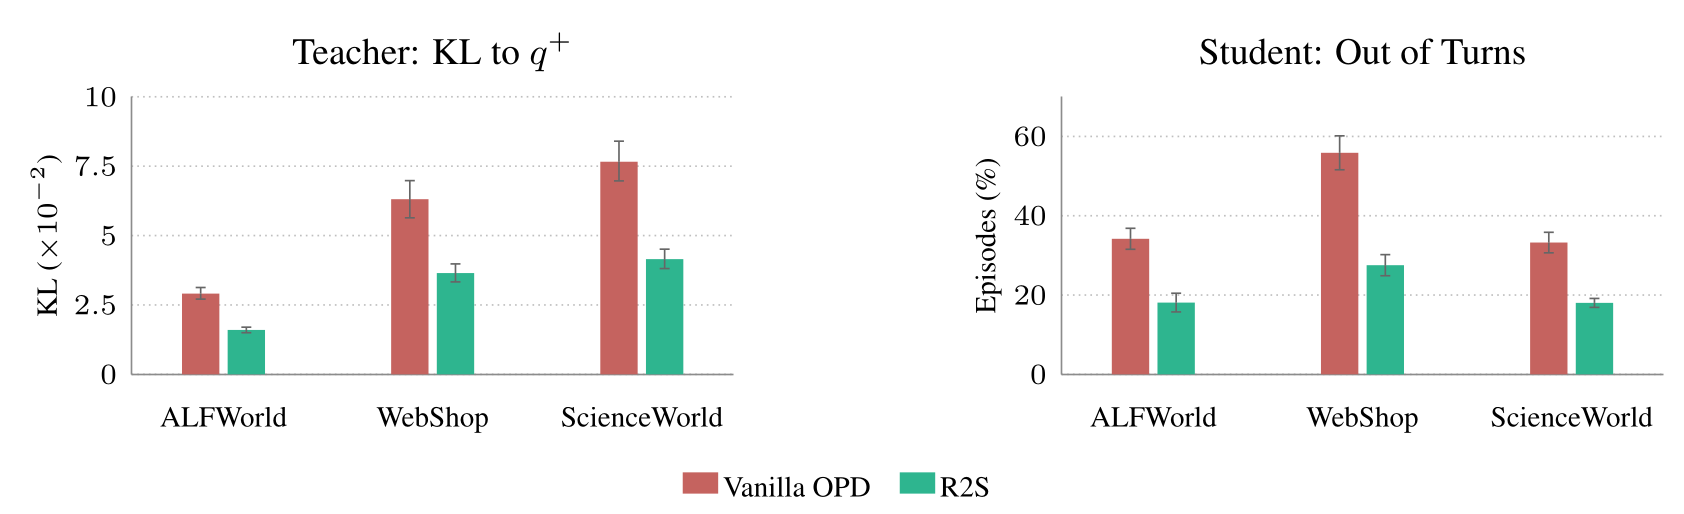
Repair moves the teacher toward its informed targets, and its student runs out of turns about half as often. Left: each teacher's top-16 KL to q+ on held-out states, with 95% goal-bootstrap intervals. Right: held-out episodes that end unfinished at the turn budget, mean ± std over three decodes.
The 24 checkpoints of the main table, on the Hugging Face Hub as bf16 safetensors. The repaired teacher of a pair is the sole scorer that distilled that pair's student; the student is the final checkpoint of its 150-step run. The "Teacher alone" row of the table is the unrepaired base teacher.
@article{zhao2026capable,
title={Capable Teacher, Myopic Scorer: Reward-Free Teacher Repair for Agentic On-Policy Distillation},
author={Zhao, Shu and Yu, Tan},
journal={arXiv preprint arXiv:2610.28586},
year={2026}
}